
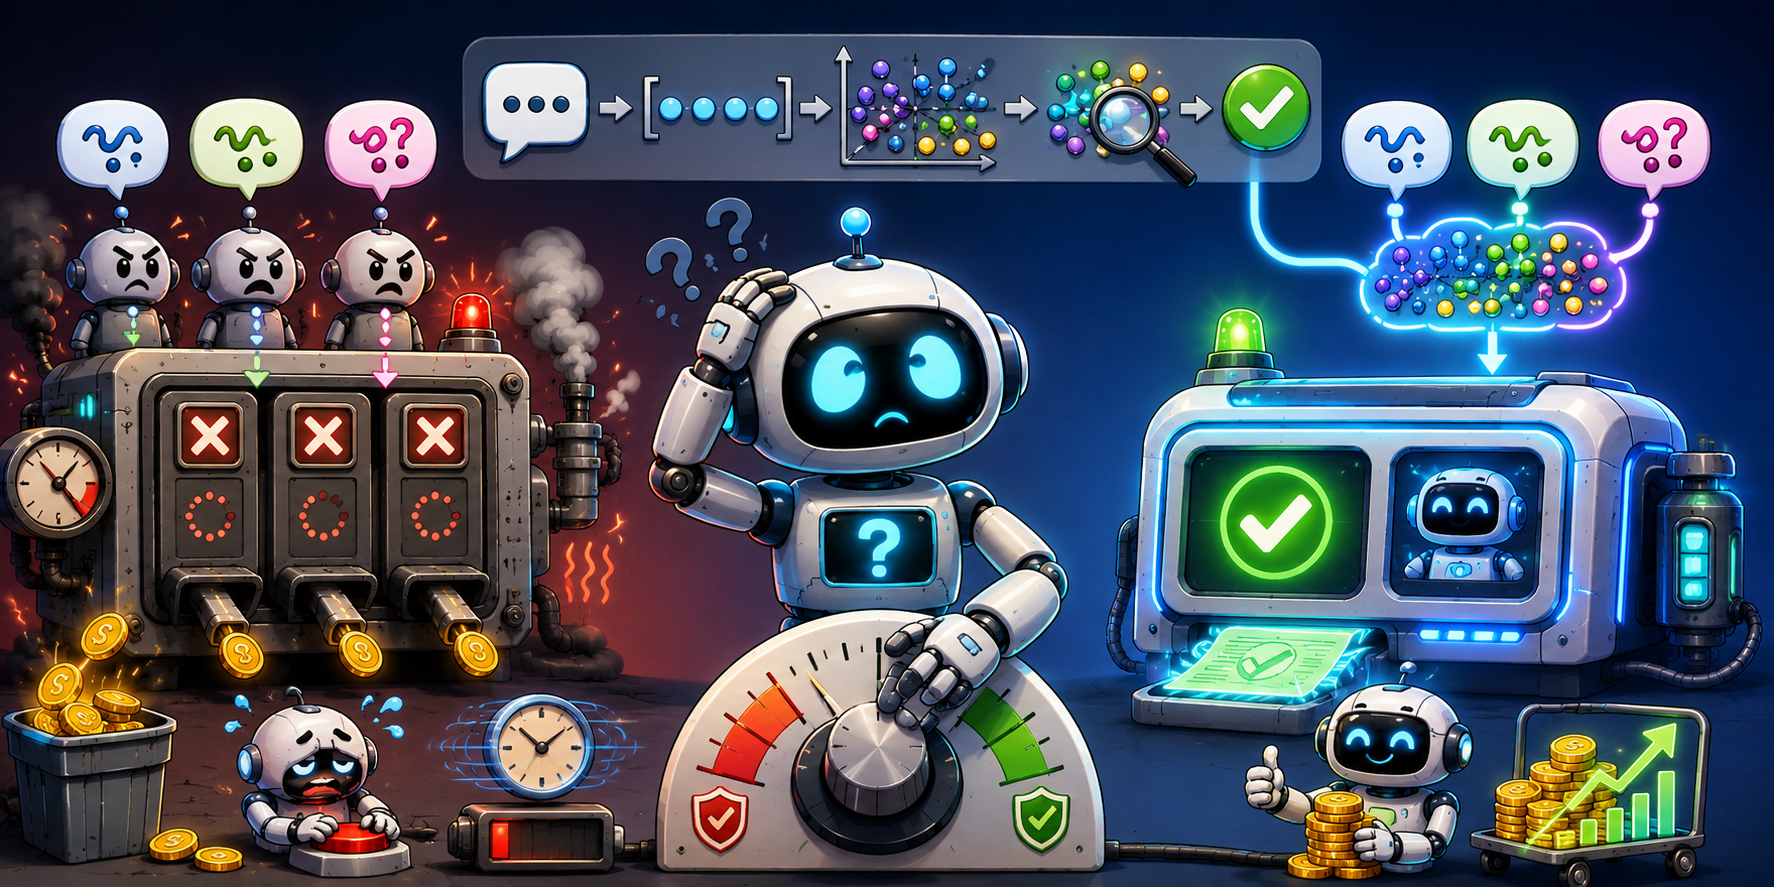
Large Language Models keep getting better, and they keep getting pricier and slower at the top end. If you are shipping anything on GPT-5 or Claude, the reasoning-grade models cost real money per token and they are not fast. For most teams I talk to, inference has quietly become the largest cost item in the system and not storage, not the vector DB, not the plumbing.
Agents make it worse. An agent doesn’t answer once. It plans, calls a tool, reads the result, second-guesses itself, and goes around again, and every lap is another LLM call. TheAgentCompany benchmark (Xu et al., 2024; later published at NeurIPS 2025) put some end-to-end agent tasks at $6.80 a run. Now picture a customer-support queue where a few hundred people ask what is basically the same question, worded differently, all day long.
Look at these three customer questions:
"How do I get a refund?"
"I want my money back"
"What is your refund policy?"
A person reads those as one question. A normal cache reads them as three different strings and misses all three.
Why the obvious cache doesn’t work
Caching is an old idea. Before you do expensive work, check whether you already did it, and if so hand back the saved answer.
# Traditional exact-match cache — matches on the raw string
cache = {}

def get_answer(query):
    if query in cache:           # only fires if the text is identical
        return cache[query]
    answer = call_llm(query)
    cache[query] = answer
    return answer
On natural language this almost never fires. The precision is perfect and the recall is close to zero, because two people mostly never type the exact same sentence. All three refund phrasings above sail straight past it and hit the model.
Semantic caching matches on what the question means instead of how it is spelled. You gain a lot of recall but also take on a new failure mode: false positives, where the cache is confident and wrong. Most of the rest of this post is about controlling that risk.
The basic loop
1. Embed the incoming question  → a vector
2. Vector-search it against everything already in the cache
3. If the nearest match is close enough (distance < threshold):
      return the stored answer      (cache HIT)
  otherwise:
      call the LLM, then store the new Q&A  (cache MISS)
It all rests on vector search. Embeddings turn text into lists of numbers that carry meaning, so questions that mean the same thing land near each other in that space. One number decides everything downstream, and that is the distance threshold. Keep an eye on it, because it comes back in every section.
Part 1: build one from scratch
Start with an FAQ dataset of question and answer pairs, plus an embedding model.
import numpy as np
from sentence_transformers import SentenceTransformer

model = SentenceTransformer("all-mpnet-base-v2")

faq_questions = ["How do I get a refund?", "Where is my order?", ...]
faq_embeddings = model.encode(faq_questions)   # shape: [n_faqs, dim]

Two small functions get you search:

def cosine_distance(a, b):
    a, b = np.asarray(a), np.asarray(b)
    cos_sim = (a @ b.T) / (np.linalg.norm(a) * np.linalg.norm(b))
    return 1 - cos_sim

def semantic_search(query):
    q = model.encode([query])[0]
    distances = [cosine_distance(q, faq_emb) for faq_emb in faq_embeddings]
    idx = int(np.argmin(distances))     # nearest FAQ
    return idx, distances[idx]

Add the threshold and you have a cache:

def check_cache(query, threshold):
    idx, distance = semantic_search(query)
    if distance < threshold:            # near enough, call it a hit
        return faq_questions[idx], faq_answers[idx], distance
    return None                         # miss

# "How long will it take to get a refund for my order?"
#   → nearest FAQ: "How do I get a refund?"  distance 0.331
# "Is it possible to get a refund?"
#   → hit at distance 0.262

And you grow it as new questions get answered:

def add_to_cache(question, answer):
    faq_questions.append(question)
    faq_answers.append(answer)
    global faq_embeddings
    faq_embeddings = np.vstack([faq_embeddings, model.encode([question])])
Everything after this is making it accurate, fast, and getting it production ready.
Part 2: move it onto Redis
A Python loop over every embedding is fine for a demo and hopeless at scale. Redis (the name is short for Remote Dictionary Server) is an in-memory database that can index vectors alongside text, numbers, and tags, so it does the low-latency vector search and holds the cache in one place. The redisvl SDK wraps it with the ergonomics you want: TTL, eviction, per-tenant namespaces.
This is also where you swap the general-purpose embedding model for langcache-embed-v1, an open-weight model that was fine-tuned specifically for cache matching.
from redisvl.extensions.cache.llm import SemanticCache
from redisvl.utils.vectorize import HFTextVectorizer

vectorizer = HFTextVectorizer(model="redis/langcache-embed-v1")

cache = SemanticCache(
    name="customer_support",        # its own namespace in Redis
    vectorizer=vectorizer,
    redis_url="redis://localhost:6379",
    distance_threshold=0.3,         # the knob, again
)

for q, a in faq_pairs:              # hydrate from the FAQ set
    cache.store(prompt=q, response=a)

hits = cache.check(prompt="I need a refund for my purchase")
# matches "How do I get a refund?" at distance 0.25 < 0.3  → hit
Two things you get almost for free here matter a lot in production. TTL, so entries expire and the cache doesn’t keep serving yesterday’s answer after the data changed:
cache.set_ttl(86400) # one day, in secondsAnd namespacing, so different teams or tenants can share one Redis without stepping on each other’s entries.
Wire the miss path to a model and you have the end-to-end thing:
def answer(query):
    hit = cache.check(prompt=query)
    if hit:
        return hit[0]["response"]           # ~65 ms
    response = llm.invoke(query)            # 1000+ ms
    cache.store(prompt=query, response=response)
    return response
A hit came back in about 65 ms against a second-plus for the model. Call it a 15x latency win every time you hit, and that is before you tune anything.
Part 3: measure it honestly
A cache can let you down two ways. It can be wrong (serves bad matches) or it can be useless (barely ever hits). You measure it the way you’d measure any classifier, over a labeled set of rows shaped like (query, nearest cache hit, distance, was it actually right). The labels come from a human reviewer or from an LLM playing judge.
Four numbers to watch
| Metric | What it tells you |
| Hit rate | How often you hit the cache. This is where the cost savings come from. |
| Precision | Of the hits, how many were actually correct. |
| Recall | Of the questions that should have hit, how many did. |
| F1 | A single number balancing precision and recall. |
The threshold controls the trade between the two you care about most:
- lower threshold → fewer, safer hits (precision up, recall down)
- higher threshold → more, riskier hits (recall up, precision down)
Plot the confusion matrix and you can see the two ways it goes wrong: false positives that matched but shouldn’t have, and false negatives that should have matched but the threshold was too tight. You want the counts sitting on the diagonal.
evaluator = CacheEvaluator(cache_results, labels)
evaluator.report_metrics()
# precision 0.79, recall 0.79, plus the confusion matrix

# The confusion_mask lets you pull out one category at a time:
fp = evaluator.matches_df[evaluator.get_metrics()["confusion_mask"]["false_positives"]]
# e.g. "Can I schedule a specific delivery time?" matched
#      "Can I change my delivery address?"  → close in the model, wrong in meaning
Latency, measured realisticlaly
It is tempting to put a 2 ms cache hit next to a 360 ms model call and claim a 180x speedup. That’s not correct, because you don’t hit cache every time. Weight it by how often you actually hit:
WithCacheLatency = CHR*ACL + (1 - CHR)*(ACL + ALL)

  ACL = avg cache latency      (say  11 ms)
  ALL = avg LLM latency        (say 350 ms)
  CHR = cache hit ratio        (say 30%)

→ E.g. about 256 ms vs 350 ms: a 26% drop, roughly 1.42x, at a 30% hit rate
Token savings scale the same way, with hit rate times daily volume. That product is what turns into the annual dollar figure your finance team will ask about.
Part 4: four ways to make it more accurate
1. Sweep the threshold
Don’t eyeball the threshold. Run the evaluation across a range and take the value that maximizes F1.
evaluator.report_threshold_sweep()
# best F1 at 0.2828 → precision 90%, recall 85%, hit rate 25%
2. Add a cross-encoder re-ranker
A cross-encoder reads both sentences at once, so it picks up nuance the embedding model flattens. The catch is that it outputs a score, not a searchable vector, so you can’t retrieve with it. You use it as a second stage: pull the top handful of candidates with vector search, re-rank them with the cross-encoder, keep the best one.
# The sentence pair everyone uses to show the difference:
#  "The bank raised its interest rates."
#  "The river overflowed near the bank after heavy rain."
# embedding model:  puts them fairly close (confused by 'bank')
# cross-encoder:    correctly far apart
# (cross_encoder_distance = 1 - cross_encoder_score)

cache.register_reranker(cross_encoder)      # a modernbert-base reranker
results = cache.check_many(test_queries, distance_threshold=1.0, num_results=10)
# → precision 94%, recall 79%, hit rate 23%
Precision jumps, and it jumps further if you fine-tune the reranker on your own pairs. You pay for it in latency, since every candidate set now goes through a second model.
Rama Krishna Raju Samantapudi, the author of this text, is going to be a speaker during the upcoming AI Loves Data San Francisco event. Secure your spot today!
3. Ask an LLM to double-check
For the hits sitting in the ambiguous middle of the distance range, ask a cheap model the simplest possible question: do these two sentences mean the same thing? Checking similarity burns far fewer tokens than generating a full answer, so it stays cheap, and you can wire it as a fallback that only fires on borderline cases rather than on every query.
cache.register_reranker(LLMEvaluator(model="gpt-4o-mini"))
# → precision 100% (every false positive gone)
#   recall drops (it rejects some real hits too), hit rate still ~21%
4. Fuzzy matching, sitting out front
Edit-distance matching catches typos before you spend a cent on embeddings. It is a plain short-circuit for keyword-ish domains.
        [ user query ]
              |
    +--------v--------+
    |  fuzzy match?   |  high threshold  → hit, skip embeddings entirely
    +--------+--------+
              | no
    +--------v--------+
    | embed + vector  |  → semantic cache
    |     search      |
    +-----------------+
On a deliberately typo-fied FAQ set, fuzzy matching at a 0.6 threshold hit 100% precision and 94% recall. It is a contrived example, but it makes the ordering point: cheap filters first, expensive ones last, so most queries never reach the slow stages.
This is exactly the shape Walmart described in their waLLMartCache paper: a load balancer for horizontal scale, two storage tiers (a vector DB for search, Redis for the lookup), multi-tenancy, and a decision engine that routes code snippets and time-sensitive questions around the cache before semantic search ever runs. Stacking those got them to roughly 90% accuracy.
Part 5: put it inside an agent
Here is the shift in thinking for agents. Don’t just cache the final answer. An agent runs through a lot of intermediate steps, and most of them are reusable: the user profile it looked up, the output of a tool call, a plan it generated, a chunk of reasoning. Cache those too, with a short TTL on anything derived from data that moves.
Redis’s own dataframe-explorer agent caches the Python code it generates and even its notes on fixing errors it has seen before, so a similar question reuses the code instead of writing it again from scratch.
For Example, in a deep-research support agent in Lang Graph, the trick that makes it pay off is caching at the sub-question level:
1. Decompose the user query into 3-5 sub-questions
2. Check the cache for each sub-question
3. Research only the ones that missed (knowledge-base tool)
4. Score the answer with an LLM judge (0-1); loop back up to 2x if it’s weak
5. Synthesize the pieces into one personalized answer
6. Write every validated sub-answer back so the next run is cheaper
In LangGraph that is nodes and edges, with a conditional edge after the cache check that skips research entirely when everything was already cached:
workflow.add_conditional_edges(
    "check_cache",
    lambda state: "research" if state["uncached"] else "synthesize",
)
Payoff across three users (and their requests)
To see the payoff, let’s take the same agent that handled three requests back-to-back, from three users at different stages of the same buying journey with overlapping questions an earlier request had already triggered (rate limits, integrations, compliance, and so on). All three shared one cache, seeded with the 8 base FAQ entries but not yet enriched by any agent runs. That seed is why even the first run gets a hit or two. The warming comes from each run writing its new, quality-checked sub-answers back, so later runs reuse both the seed and whatever earlier runs figured out. Read the table top to bottom as time moves forward.
| Run | Cache hit rate | LLM calls | Latency |
| 1 (seed only) | 25% | 8 | ~20 s |
| 2 | 75% | 4 | ~13 s |
| 3 | 75% | 6 | ~18 s |
Row 1 is the baseline: what a request costs when the cache only holds the seed FAQs and hasn’t learned anything yet, Rows 2 and 3 are what the same kind of request costs once earlier runs have filled the cache in. Model calls went from eight on the first run to four and six on the later ones, a 40-50% cut once the cache had something in it, and latency dropped to a third.
The 60% cumulative hit rate is not the average of 25, 75, and 75. It is the blended rate over every sub-question across all three runs pooled together. Weighted by total sub-questions answered, the system served about three of every five straight from cache, starting from a seed of only some 8 FAQs.
One thing worth explaining, run 3 costs more than run 2, six calls instead of four and a few seconds slower, even though both hit the cache 75% of the time. Both runs had exactly one sub-question miss and go to research. The difference is how hard that one leftover question was. In run 2 the missed question passed on the first try, one research-and-check cycle. In run 3 it failed the first check and went around a second time, so two cycles, which is the extra two calls and the extra few seconds. Hit rate tells you how many questions you got to skip. It says nothing about how expensive the ones you didn’t skip turn out to be.
The cache only ever serves sub-answers that already cleared the quality judge. Run that across thousands of users instead of three and the cache pays for itself many times over.
What to remember
- Exact-match caching is a non-starter for natural language. You need meaning, which means embeddings and vector search.
- The distance threshold runs the whole show, trading precision against recall. Sweep for it, don’t guess.
- Measure it like a classifier: hit rate, precision, recall, F1, a confusion matrix, and a latency number weighted by how often you actually hit.
- Order your accuracy boosters cheapest first: fuzzy match, then vector search, then a cross-encoder, then an LLM check.
- Inside an agent, cache the intermediate steps, not just the final reply. The cache warms up and every run after gets cheaper.
The thing agents are worst at, chewing through expensive multi-step reasoning over questions they have basically answered before, is exactly the thing a semantic cache turns into a strength.
Author: Rama Krishna Raju Samantapudi
Rama Krishna Raju Samantapudi is going to be a speaker during the upcoming AI Loves Data San Francisco event. Secure your spot today!